Qwen3-Omni Thinker GSPO recipes
Last updated: 11/09/2026
This directory contains both FSDP2 and Megatron recipes. For non-Megatron setup, data preparation and training instructions, see the parent GSPO guide. The launchers below contain each recipe’s defaults and accept CLI overrides.
Recipe |
Backend / platform |
Launcher |
|---|---|---|
GSM8K LoRA |
FSDP2 / GPU |
|
MMK12 LoRA |
FSDP2 / GPU |
|
MMK12 LoRA, separate-async |
FSDP2 / GPU |
|
MMK12 LoRA |
FSDP2 / NPU |
|
MMK12 LoRA with on-policy distillation |
FSDP2 / NPU |
|
AVQA LoRA |
FSDP2 / GPU |
|
AVQA full-parameter |
FSDP2 / NPU |
|
NExT-QA full-parameter |
FSDP2 / NPU |
|
AudioMCQ full-parameter, separate-async |
Megatron / GPU |
|
AVQA image+audio full-parameter, separate-async |
Megatron / GPU |
|
Geo3K full-parameter, separate-async |
Megatron / GPU |
The following sections describe the Megatron AudioMCQ, AVQA, and Geo3K recipes, their dependency prerequisites and validation limits. For model-adapter development, see the Megatron integration notes.
AudioMCQ with Megatron and V1 separate-async rollout
This recipe trains all Thinker language-model parameters (LoRA rank zero),
freezes the vision/audio towers, and generates text conditioned on audio with
standalone vLLM-Omni replicas. It uses trainer.v1.trainer_mode=omni_separate_async.
The toy smoke and full-model run both select the shared
verl_omni/trainer/config/omni_megatron_trainer.yaml; the public launcher adds
only the AudioMCQ recipe overrides, and the toy adds its small-model overrides.
OmniMegatronEngine follows verl’s Megatron LM forward flow and selects its
model-specific config preparation and forward through the registered pipeline
adapter. The Qwen3-Omni pipeline owns the support checks, config mapping and
explicit BSHD model call that passes audio tensors and lets the Thinker build M-RoPE.
It uses BSHD, PP1 and CP1;
the development audio bridge does not implement packed sequences, dynamic
micro-batching is disabled, and MTP, dynamic CP and router replay are rejected.
Optimizer, old-policy snapshots, losses and weight export remain
upstream implementations.
An engine-private config view exposes the nested Thinker text dimensions to
upstream Megatron helpers without changing the worker/rollout HF configuration.
Environment and data
Use the repository’s pinned verl/vLLM-Omni runtime and install the audio extra
(uv pip install -e '.[audio]'). Megatron also requires a compatible Megatron-Core,
Transformer Engine, and Megatron-Bridge with Qwen3-Omni audio forward/export
support. The recipe selects use_mbridge=true.
Upstream Megatron-Bridge already includes Qwen3-Omni Thinker conversion,
audio-input forwarding, and checkpoint import/export from
#3317. Its main
branch also has the Transformers 5 registration fix from
#4876 and computes
audio feature lengths with the current n_window-aware formula for this
recipe’s one-audio-per-row inputs. Release
v0.6.2 still uses the older audio encoder length method, so select and test
a Bridge/Megatron-Core revision with the current audio-length behavior before
claiming clean-checkout reproduction. The H200 acceptance run used a development
Bridge/Megatron-Core pair; its success does not validate the repository’s
current public pins. Native Transformer Engine and FlashAttention extensions
must be built for that environment’s PyTorch version.
The full-model TransferQueue path also needs the equal-length 3D position-ID
layout repair tracked by verl #7901.
The development run used the implementation from closed
verl #7767, head a965a838.
TransferQueue 0.1.8 can carry [4, sequence_length] position IDs whose jagged
layout is inconsistent; the old verl helper changes only _ragged_idx without
rebuilding values and offsets. This can fail before the model forward even
though the Thinker ultimately constructs its own M-RoPE. Keep the repair in
verl rather than duplicating it in the Omni trainer.
Merge prerequisites
This full-model recipe is not reproducible from the repository pins yet. The following dependency work must land before this PR can be treated as runnable from a clean checkout:
verl-project/verlmust replace itsmegatron-bridge==0.5.2and paired Megatron-Core pins with a tested upstream pair that includes the already upstream Qwen3-Omni support and current audio-length handling. Then this repository must bump.github/verl_pin.txtto that verl revision.verl #7901, or an equivalent replacement for closed verl #7767, must land with regression coverage for equal-length multimodal position IDs, followed by the same verl pin bump here.
The 150-step acceptance run used the development dependency overrides described above; it validates this integration path but is not evidence that the public pins already satisfy these prerequisites. The tiny-random smoke validates audio transport, optimizer steps, and weight synchronization only. It does not exercise the full-model TransferQueue position-ID failure and must not be used as evidence that the dependency issue is fixed.
Keep the recipe’s limit_mm_per_prompt.image=1 even for audio-only data. With
both image and video limits zero, the pinned vLLM-Omni creates vision deepstack
buffers on meta but still consumes them during audio/text profiling. Keeping
vision resident avoids that device mismatch at the cost of extra inference
memory. This does not add image samples or unfreeze either tower. The shared
server’s existing frontend multimodal-cache reset must also run after sleep;
direct AsyncOmni.sleep() alone does not cover that server lifecycle.
Download the AudioMCQ-StrongAC-GeminiCoT dataset and audio assets
separately. Its dataset card
lists Apache-2.0; check the terms of the underlying audio sources as well.
Prepare a local data.jsonl containing question, choices, answer,
audio_path, and optional source_dataset/id fields:
python examples/gspo_trainer/data_process/audiomcq.py \
  --input-jsonl /data/AudioMCQ/data.jsonl \
  --audio-root /data/AudioMCQ \
  --output-dir /data/audiomcq-prepared \
  --validation-size 256 --seed 42
Conversion checks file existence, labels and path containment; it does not
decode the entire audio corpus. Missing/invalid rows are counted in
dataset_info.json. Validation holds out 256 unique audio assets; questions
sharing an asset stay in the same split. Existing output files are never
overwritten; use a new output directory for each conversion. Audio paths must
be accessible at the same location on all nodes.
Previously audited AudioMCQ parquets with prompt, audios, and structured
reward_model.ground_truth can be used directly to preserve their exact split.
The scorer accepts exact option text or an option letter inside <answer> and
reports content_correct and format_valid. It preserves the development
recipe’s reward semantics, including its handling of repeated answer tags.
Toy smoke (4 GPUs)
bash tests/special_e2e/run_qwen3_omni_megatron_audiomcq_smoke.sh
Builds the existing multimodal tiny-random Qwen3-Omni checkpoint and short
synthetic PCM WAVs locally. Uses 2 Megatron training GPUs plus a standalone TP2
replica on 2 GPUs, four optimizer steps, sync every two steps, and validation
before training and every two steps. Keeping two updates per sync exercises
V1’s old-policy parameter save/restore. Synthetic tones test audio transport
only. Random-model correctness and nonzero reward are not acceptance gates.
Inspect finite losses/logprobs, successful optimizer steps, weight transfers,
and validation completion. A zero gradient is permitted when every reward and
advantage is zero.
The toy uses top_k=1 with positive temperature: unrestricted sampling from its
tiny random vocabulary can emit input-side audio markers in the response,
creating fictitious audio segments that cannot be matched to input features.
This structural-test setting does not change the full-model sampling defaults
and is not evidence of stochastic sampling quality or a learning curve.
Full-model run (32 GPUs)
After allocating four 8-GPU nodes and starting a Ray cluster, run once on the head. The defaults request 4 training and 4 standalone rollout GPUs per node, actor TP4/EP4/PP1 (expert TP1), rollout TP4, and 150 steps with validation every 10 steps. The toy overrides actor TP/EP to one; do not use its unsharded-expert topology for the 30B run:
MODEL_PATH=/models/Qwen3-Omni-30B-A3B-Instruct \
TRAIN_FILE=/data/audiomcq-prepared/train.parquet \
VAL_FILE=/data/audiomcq-prepared/validation.parquet \
OUTPUT_DIR=/persistent/audiomcq \
bash examples/gspo_trainer/qwen3_omni/run_qwen3_omni_megatron_audiomcq_separate_async.sh \
  ray_kwargs.ray_init.address=auto
The launcher records the command, Git revision, resolved configuration, console
log and TensorBoard events in a unique run directory. Use local scratch for
high-frequency writes and archive once afterward on fragile shared filesystems.
TensorBoard and worker bootstrap environment variables are explicitly forwarded
through Ray’s per-job runtime environment, including for pre-started clusters.
Hydra overrides are forwarded unchanged; keep
data.train_batch_size == parameter_sync_step * actor.ppo_mini_batch_size.
V1 also uses hybrid replicas on the training pool for its initial sampling
window and validation. Although hybrid switching during training is disabled,
sleep/wake and colocated weight loading still need to work. Prefix caching is
disabled. The old development fully_async_policy run does not validate these
V1 lifecycle paths or Decoupled PPO (bypass_mode=false). A successful toy smoke
establishes structural coverage, not full-model learning or TP4 numerical
parity; evaluate the need for a new full-model run after reviewing the changes.
AVQA image+audio full-parameter Megatron separate-async
This AVQA launcher trains the
Qwen3-Omni Thinker language model on real image and audio inputs, with its
vision and audio towers frozen. It uses GRPO advantages, GSPO sequence clipping,
the repository’s exact choice_reward.py scorer, and the V1 separate-async
actor/rollout path. The launcher reuses omni_megatron_trainer.yaml with AVQA, model and topology
overrides; it does not invoke another task launcher. It does not train the Talker or provide a
video-training recipe.
Convert the official AVQA-R1 archive with the existing
AVQA converter. The published AVQA-R1 split used in
our validation contained media bytes shared across train and validation; its
problem_id also restarts in each split. Make a separate strict training
parquet by excluding every training row whose image or audio SHA256 occurs
in validation. Keep the original train and validation files unchanged:
python examples/gspo_trainer/data_process/avqa.py \
  --input_dir /data/avqa_r1 \
  --output_dir /data/avqa_r1_verl
python examples/gspo_trainer/data_process/avqa_strict.py \
  --train_file /data/avqa_r1_verl/train.parquet \
  --validation_file /data/avqa_r1_verl/validation.parquet \
  --output_file /data/avqa_r1_verl/train_strict.parquet \
  --audit_file /data/avqa_r1_verl/strict-audit.json
The source archive used for the H200 run yielded 4,491 original training rows, 1,911 validation rows and 4,435 strict training rows after 56 exclusions. These counts are properties of that archive, not hard-coded converter limits. The parquet files contain absolute media paths; make them accessible at the same paths to every worker. Audit processor lengths on real image+audio inputs before increasing the prompt limit or changing the media policy.
CUDA_VISIBLE_DEVICES=0,1,2,3,4,5,6,7 \
MODEL_PATH=/models/Qwen3-Omni-30B-A3B-Instruct \
TRAIN_FILE=/data/avqa_r1_verl/train_strict.parquet \
VAL_FILE=/data/avqa_r1_verl/validation.parquet \
OUTPUT_DIR=/outputs/avqa \
bash examples/gspo_trainer/qwen3_omni/run_qwen3_omni_megatron_avqa_separate_async.sh
The default single-node layout uses four Megatron actor GPUs (TP4/EP4) and four rollout GPUs (TP4), 4,096 prompt tokens, 2,048 response tokens, and 16 prompts with eight responses. Training defaults to 150 optimizer updates and complete validation every 30 updates. The actor uses a precision-aware optimizer with 100% CPU FP32 master-parameter offload to reduce GPU memory requirements; allow sufficient host RAM. The recipe saves no checkpoints and retains its resolved configuration, command, TensorBoard events, log and generations in one unique run directory.
NUM_GPUS=6 ROLLOUT_GPUS=2 ROLLOUT_TP=2 selects a six-GPU layout. Extra Hydra
arguments override the recipe settings. Ray CPU count and object-store size
are not fixed by the launcher; set them for the allocated host when needed,
for example ray_kwargs.ray_init.num_cpus=32 and
+ray_kwargs.ray_init.object_store_memory=17179869184. Communication-library
settings belong to the deployment environment rather than this recipe.
Review the resolved configuration after applying overrides.
Validation and dependencies
The current launcher completed 10 optimizer updates on eight H200 GPUs (4 actor + 4 rollout, rollout TP4), with full 1,911-question validation at steps 0 and 10. Correct answers increased from 1,454 to 1,544; strict single-choice answer formatting increased from 1,806 to 1,899. Official reward regrading found zero mismatches, and the run exited with code 0. Loss, gradient norm, entropy, rollout-correction KL and train/rollout Pearson remained finite. This short run validates the launcher changes; it does not establish long-run convergence or a backend speedup.
The standalone launcher at a21bc851 completed 30 optimizer updates on six
H200 GPUs with full 1,911-question validation at steps 0 and 30. Correct
answers increased from 1,368 to 1,543 and parseable answers from 1,715 to
1,902; official reward regrading found no mismatches. Logged loss, gradient
norm, entropy, rollout-correction KL and train/rollout Pearson were finite.
The run was intentionally stopped after the completed step-30 validation.
An earlier entry point completed 150 updates and six full validations on eight H200 GPUs: correct answers increased from 1,446 to 1,642. Its TensorBoard curves are supporting evidence, not a GPU test of every later launcher revision. Improved formatting contributes to the reward gain; these results alone do not establish improved reasoning. Compare aggregate validation scores, since generations do not have stable cross-step IDs.
These development runs used Megatron compatibility dependencies described above. The latest 10-update validation exercised the upstream CPU-snapshot function with its pin_memory calls intact; that tested configuration did not require the local snapshot change used by earlier runs. No snapshot patch is included in this recipe. Reproduction with the repository’s complete set of unmodified dependency pins remains unverified.
Focused CPU checks:
python -m pytest -q tests/utils/test_avqa_data_process_on_cpu.py \
  tests/utils/reward_score/test_choice_reward_on_cpu.py \
  tests/utils/test_avqa_strict_on_cpu.py \
  tests/trainer/omni/test_avqa_megatron_config_on_cpu.py
Geo3K image-conditioned Megatron separate-async
The standalone Geo3K launcher
reuses verl_omni/trainer/config/omni_megatron_trainer.yaml and the existing
Qwen3-Omni Megatron adapter. It trains the Thinker language model with frozen
vision/audio towers. The dependency prerequisites and BSHD/PP1/CP1 limitations
in the AudioMCQ section also apply.
Prepare Geometry3K with the
converter below. Check the dataset card and original Geometry3K license before
use. The converter preserves encoded image bytes and source question whitespace,
validates image-placeholder counts, and records the original split and row index.
It explicitly requests <think>...</think>\boxed{...}, as consumed by verl’s
built-in hiyouga/geometry3k reward (90% answer accuracy, 10% strict format).
python examples/gspo_trainer/data_process/geo3k.py --local_save_dir /data/geo3k
MODEL_PATH=/models/Qwen3-Omni-30B-A3B-Instruct \
TRAIN_FILE=/data/geo3k/train.parquet VAL_FILE=/data/geo3k/test.parquet \
OUTPUT_DIR=/outputs/geo3k \
bash examples/gspo_trainer/qwen3_omni/run_qwen3_omni_megatron_geo3k_separate_async.sh
Defaults use eight GPUs: four TP4/EP4 actor GPUs and four TP4 rollout GPUs,
GRPO advantages with GSPO clipping (0.0003/0.0004), LR 1e-6, and 16 prompts
with 8 samples each. Prompt/response limits are 1024/3072 tokens; old-policy and
actor microbatches are both one. Dynamic batching, remove padding, reference KL
and LR warmup are disabled. Precision-aware optimization offloads FP32 optimizer
states to CPU; the trajectory-lag threshold is one. The launcher requests 150
updates, full validation before training and every 10 updates, and no checkpoints.
Each launch retains its command, resolved configuration, TensorBoard, log and
generations in a unique directory. CLI overrides remain last; preprocessing
requires --overwrite to replace existing parquet files.
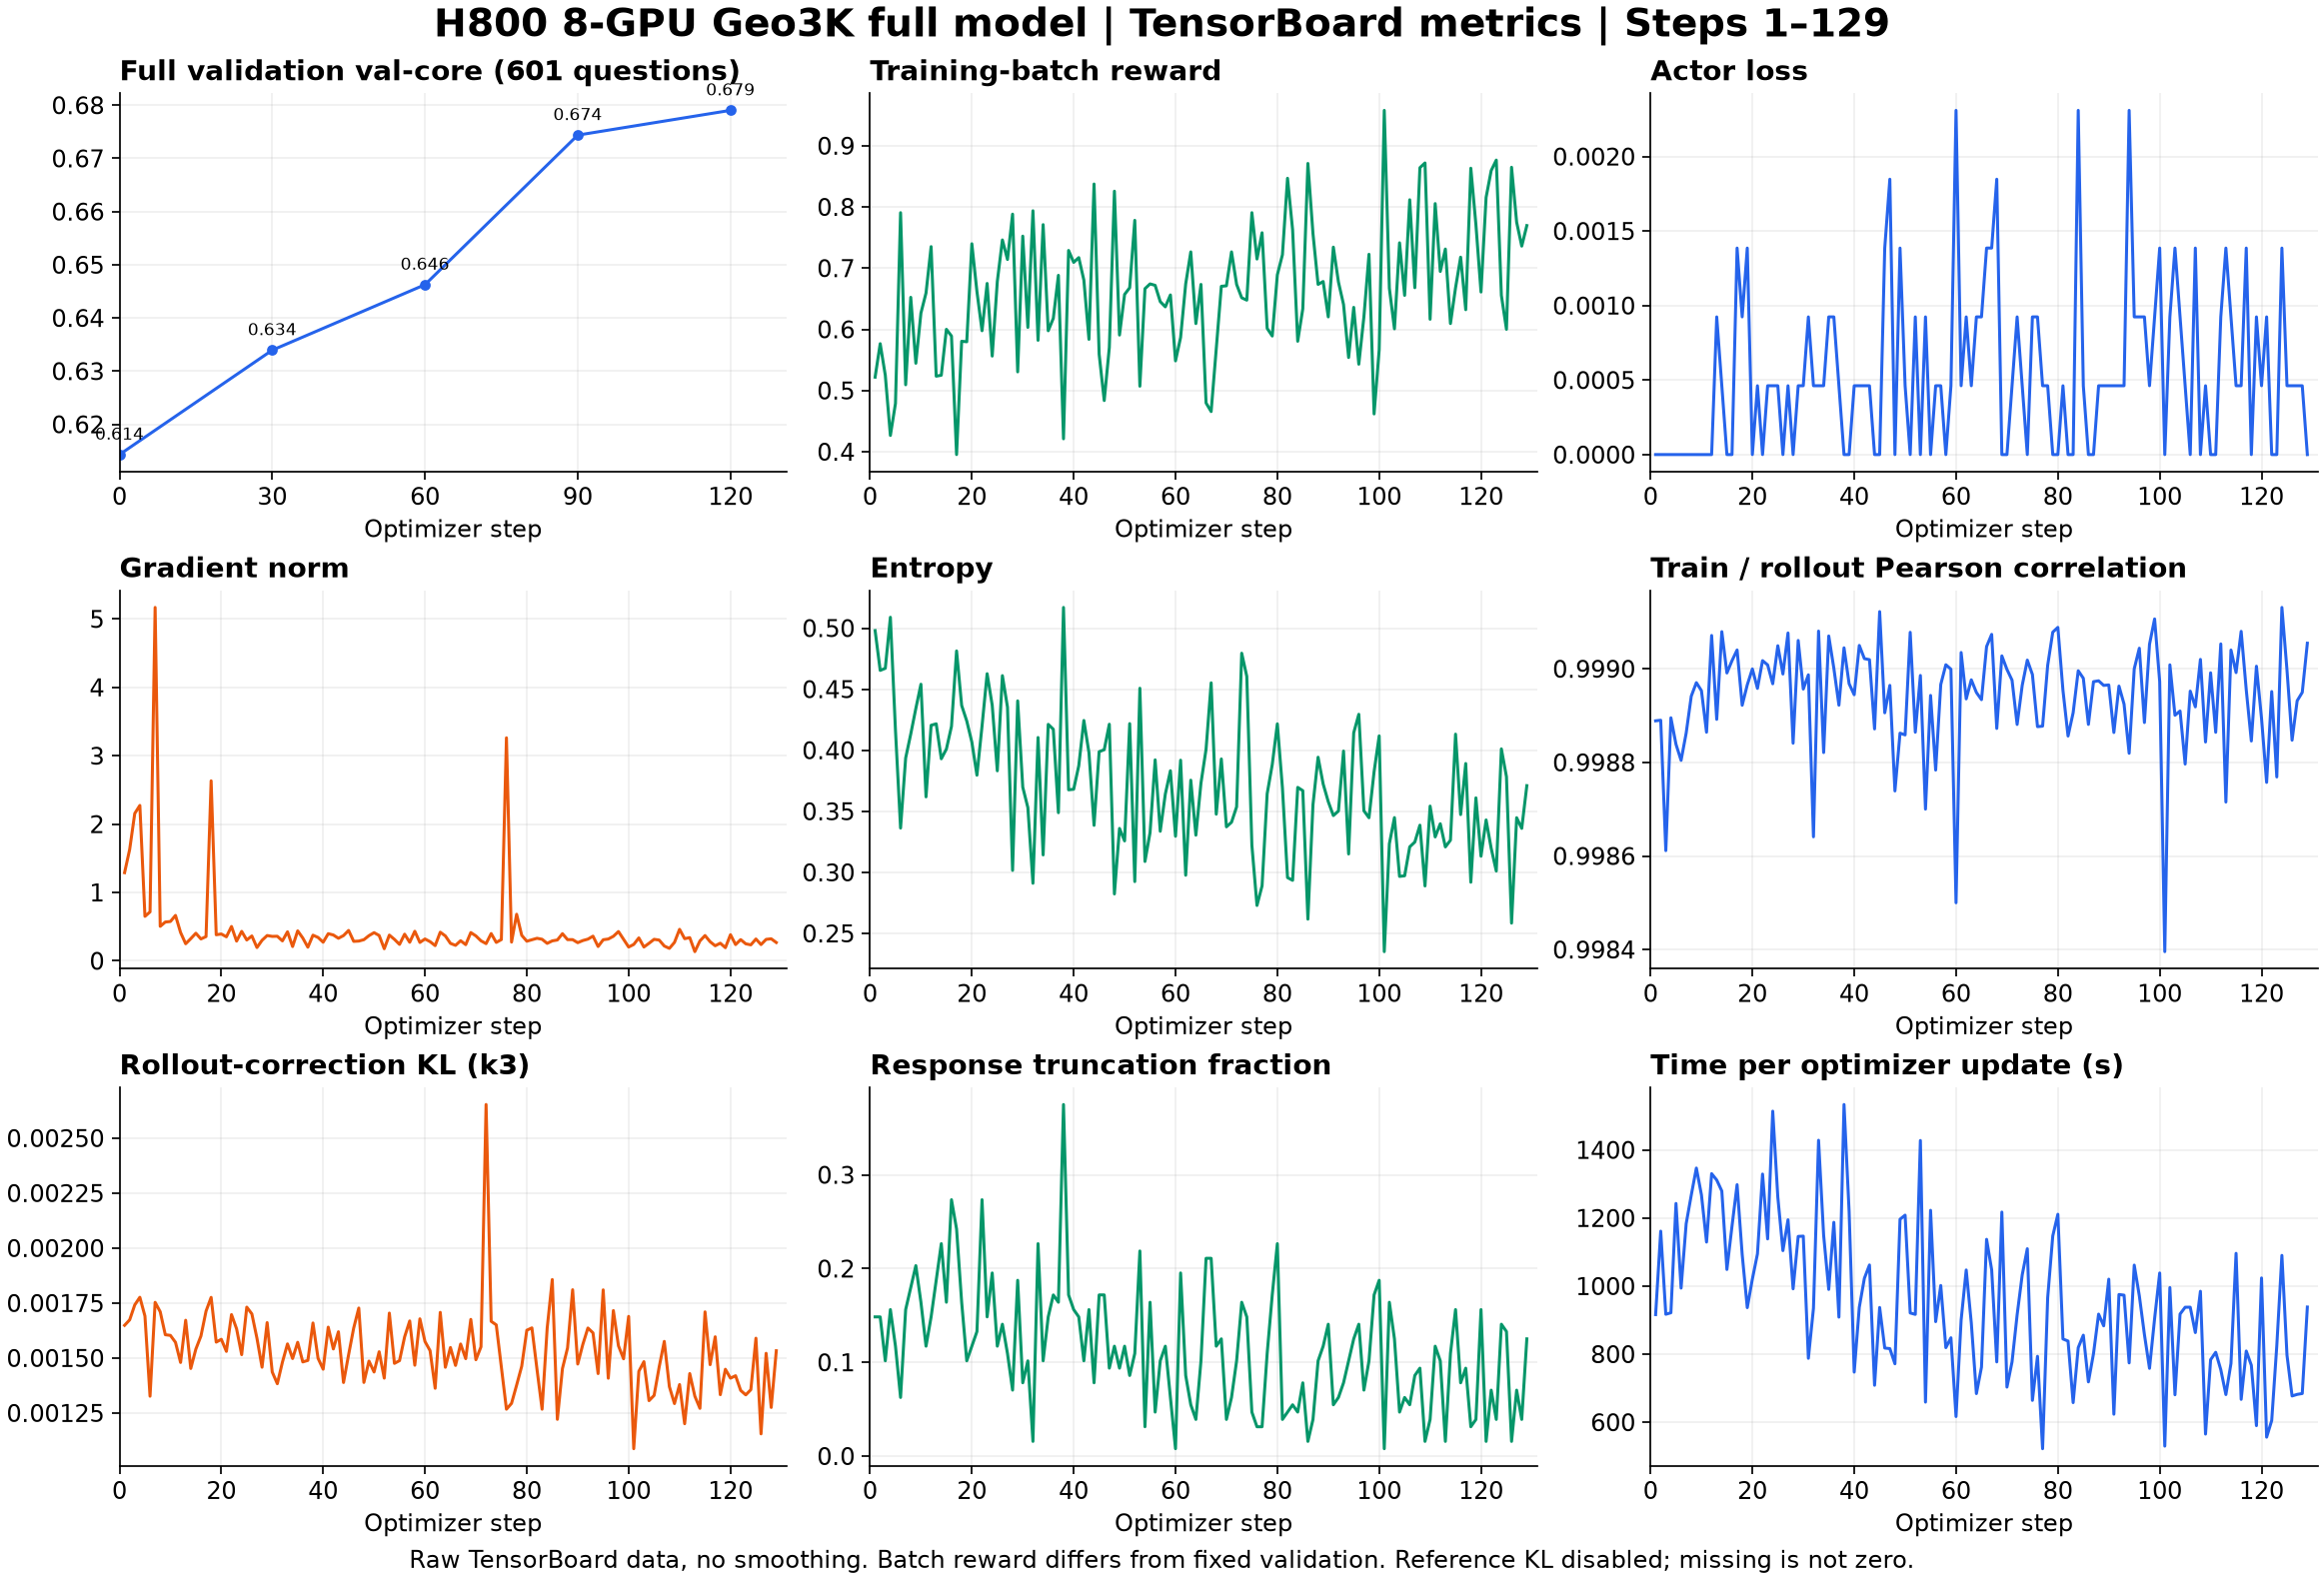
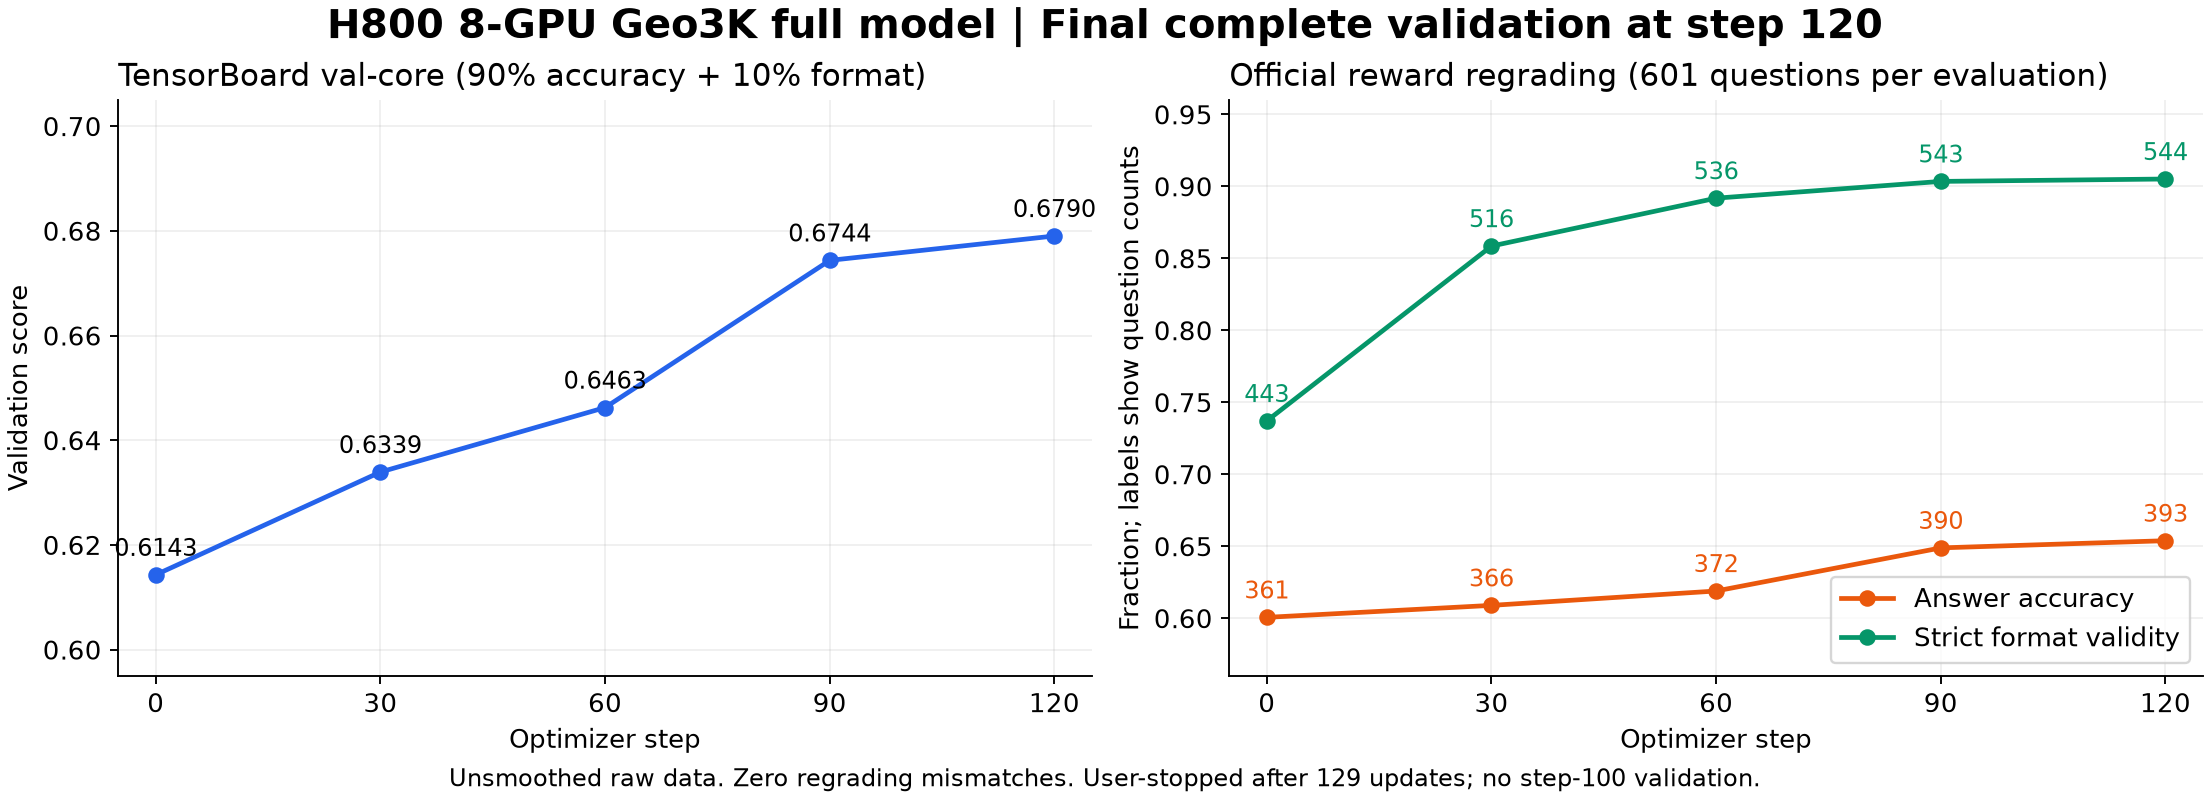
An eight-H800 development run completed 129 optimizer updates before a user-requested
stop (exit -15). Full 601-question validation ran at steps 0/30/60/90/120.
Validation reward increased from 0.614309 to 0.679035: correct answers rose
from 361 to 393 and strict-format answers from 443 to 544. Official reward
regrading had zero mismatches. The English-only figure shows unsmoothed validation
reward (90% answer accuracy, 10% strict format) and its two components.
See the full TensorBoard metrics for training-batch reward and other diagnostics. This run used an earlier entry point, development dependencies and recorded overrides; it does not establish exact-head reproduction of the final launcher with unchanged public pins.