Performance Reference
Last updated: 09/10/2026
Below are reference benchmark results for VeRL-Omni training runs.
Diffusion actor output retention
The FSDP/FSDP2 PPO and NFT engines discard per-timestep model outputs after backward during ordinary training. Losses and metrics are still aggregated, but unused prediction/latent tensors are not retained and stacked across all timesteps and micro-batches. Forward-only calls keep their complete outputs, including reference-policy inference.
Direct engine callers that need outputs during training can opt in using the
existing verl batch metadata: tu.assign_non_tensor(batch, return_model_output=True).
The engine result retains the model_output key; it is an empty dictionary when
outputs are discarded. The training worker continues to return metrics only.
This changes output lifetime, not the loss, gradient accumulation, input-trajectory placement, or DPO’s one-shot update. It does not make total device memory independent of trajectory length; capacity and throughput gains require workload-specific measurement.
Opt-in timestep input staging
For Qwen-Image FlowGRPO or DiffusionNFT training with FSDP/FSDP2 on GPU and
ulysses_sequence_parallel_size=1, enable:
actor_rollout_ref.actor.enable_timestep_staging=true
This default-false option keeps the caller’s trajectory on CPU, copies shared prompt conditions once per micro-batch, and transfers only the current step’s inputs before forward/backward. PPO transfers the current/next latent pair and matching loss fields; NFT keeps the clean latent and any shared noise on device and transfers per-step noise when supplied. Dtypes, step order and gradient accumulation are unchanged. Unused driver tensors are not copied to the device. Consumed tensor inputs must be on CPU and must not require gradients.
The validated scope is QwenImagePipeline with flow_grpo or diffusion_nft
on GPU, FSDP/FSDP2 and SP=1; see the
Qwen-Image README.
The shared engine does not enforce a model/device allowlist; trainer config
validation rejects sequence parallelism. Inference keeps its existing input/output behavior. Training output
opt-in still works, but retaining those outputs reintroduces trajectory-length
dependent output memory.
Direct engine callers can set tu.assign_non_tensor(batch, enable_timestep_staging=True)
on a training batch. The public actor worker supplies this metadata from its actor
configuration; the reference engine uses the unchanged upstream FSDPEngineConfig.
Transfers are synchronous: there is no prefetch, pinned-memory pool, or overlap guarantee. Full CPU trajectory storage is unchanged. Measure both peak allocated/ reserved device memory and update time on the intended workload before choosing this memory-for-transfer-cost tradeoff; staging is not a throughput guarantee.
DAPO Phase 1: LoRA Training on Qwen3-Omni Thinker AVQA
This reference uses the Thinker DAPO Phase-1 recipe: vanilla token-level clipping with GRPO advantages, without dynamic sampling or overlong reward shaping. It is a single-seed run on AVQA, not the full DAPO recipe.
Experiment Settings
Setting |
Value |
|---|---|
Model |
|
Hardware / actor |
4 × NVIDIA A800, FSDP2 LoRA |
Dataset / reward |
AVQA; |
LoRA rank / alpha |
32 / 64 |
Learning rate / train batch size |
|
Rollout samples / tensor parallel size |
|
Policy loss / clipping / aggregation |
|
Advantage estimator / KL |
GRPO / disabled |
Data seed |
42 |
Validation |
All 1,911 AVQA examples, before training and every 10 steps |
Validation decoding |
Greedy: |
Long-Run Validation Reward
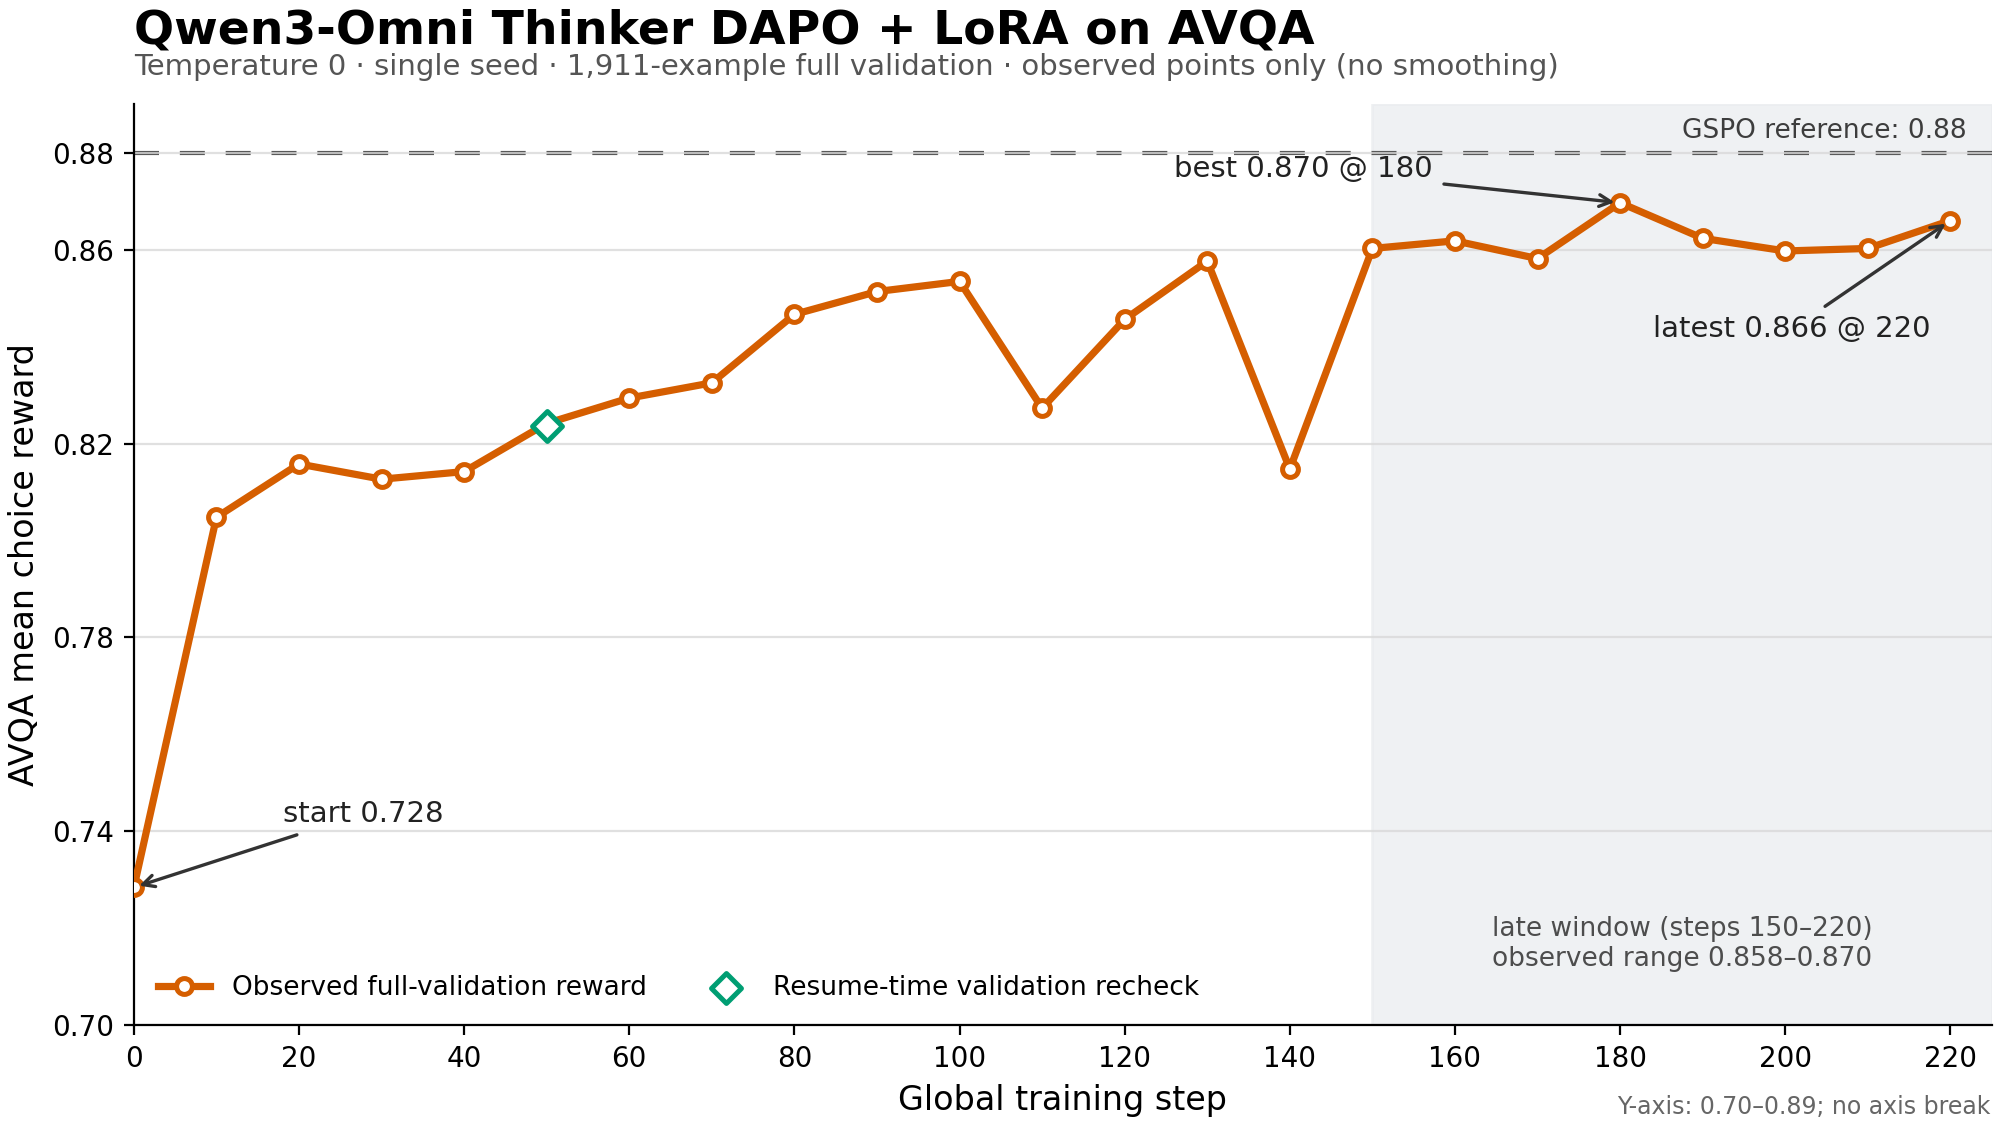
The run was resumed from step 50 and continued through step 235 without changing or tuning the training configuration. The recorded full-validation curve extends through step 220; each point is the mean choice reward over the same validation set.
Checkpoint |
Step |
Validation reward |
|---|---|---|
Initial |
0 |
0.728414 |
Initial run end |
50 |
0.824176 |
Best observed |
180 |
0.869702 |
Latest recorded validation |
220 |
0.866039 |
Validation reward improved by 14.1287 percentage points from the initial to the
best checkpoint. At steps 150–220, it fluctuated between 0.858189 and 0.869702.
The curve shows observed values without smoothing or interpolation; it does not
reach the GSPO+LoRA reference value of 0.88 in this window.
The GSPO reference uses a different validation sampling configuration
(temperature=1.0, top_p=0.7, top_k=-1). Re-evaluating the retained
step-50/150/200 checkpoints with that tuple gave 0.821559 / 0.856096 /
0.859759, versus 0.824176 / 0.860283 / 0.859759 with greedy decoding.
These single-seed, single-decode observations do not establish GSPO performance
parity or a systematic advantage for either validation temperature.
The experiment used implementation commit
c4671984.
See the long-run evidence and configuration comparison
for the run record; later documentation updates do not change its tested revision.
FlowGRPO: LoRA Training on Qwen-Image OCR
All experiments used NVIDIA H800 GPUs, LoRA rank 64,
ppo_micro_batch_size_per_gpu16, and the full 1k validation set. Training images per step = batch size × images per prompt = 32 × 16 = 512.
Experiment Settings and Throughput
Script |
# GPUs |
# GPUs for Actor |
# GPUs for Rollout |
# GPUs for Async Reward |
Batch Size |
Images per Prompt |
LR |
Throughput (images/GPU/s) |
Time per Step (s) |
|---|---|---|---|---|---|---|---|---|---|
|
4 |
4 |
4 |
0 (sync) |
32 |
16 |
3e-4 |
0.305 |
420 |
|
5 |
4 |
4 |
1 |
32 |
16 |
3e-4 |
0.280 |
360 |
Training - Zero Standard Deviation Ratio and Reward Curve
qwen_image_ocr_lora: sync reward, 4 GPUs (run_qwen_image_ocr_lora.sh)qwen_image_ocr_lora_async_reward: async reward on a dedicated 5th GPU (run_qwen_image_ocr_lora_async_reward.sh)
Validation Reward Curve
Evaluated with trainer.val_before_train=True:
qwen_image_ocr_lora: sync reward, 4 GPUs (run_qwen_image_ocr_lora.sh)qwen_image_ocr_lora_async_reward: async reward on a dedicated 5th GPU (run_qwen_image_ocr_lora_async_reward.sh)
Note: Reward curves may differ from the references above mainly due to rollout-side stochasticity: diffusion rollouts sample random latents/noise, and the example scripts do not fix the data seed, so prompt ordering can vary between runs.
FlowGRPO: non-CFG Full Model Training on Qwen-Image OCR
Experiments used NVIDIA H200 GPUs, lr 3e-5, clip_ratio 1e-5, optimizer state fp32. The other parameters are consistent with the LoRA setting.
Note that the initial reward is expected to be low for non-CFG full model training.
Full-Model Experiment Settings and Throughput
Script |
# GPUs |
# GPUs for Actor |
# GPUs for Rollout |
# GPUs for Async Reward |
Batch Size |
Images per Prompt |
LR |
Throughput (images/GPU/s) |
Time per Step (s) |
|---|---|---|---|---|---|---|---|---|---|
|
4 |
4 |
4 |
0 (sync) |
32 |
16 |
3e-5 |
0.510 |
250 |
Reference wandb curve here.
Full-Model Training - Zero Standard Deviation Ratio and Reward Curve
Training - Clip Fraction
Full-Model Validation Reward Curve
FlowGRPO non-CFG Full Model: VeOmni vs FSDP1 Backend (same config)
Apples-to-apples comparison: the VeOmni and FSDP1 actor engines run the same FlowGRPO recipe — same algorithm, data, and hyper-parameters — on the same hardware (64 × NVIDIA H100), differing only in the training engine. lr 3e-5, clip_ratio 1e-5, optimizer state fp32; other parameters match the LoRA setting.
FSDP1 —
run_qwen_image_ocr.shVeOmni —
run_qwen_image_ocr_veomni.sh(see the optional engine backends)
Settings and Throughput
Backend |
Script |
GPU name |
# GPUs |
# GPUs for Actor |
# GPUs for Rollout |
# GPUs for Async Reward |
Batch Size |
Images per Prompt |
LR |
Throughput (images/GPU/s) |
Time per Step (s) |
|---|---|---|---|---|---|---|---|---|---|---|---|
VeOmni |
|
H100 |
64 |
64 |
64 |
0 (sync) |
32 |
16 |
3e-5 |
0.079 |
100 |
FSDP1 |
|
H100 |
64 |
64 |
64 |
0 (sync) |
32 |
16 |
3e-5 |
0.077 |
105 |
Note: VeOmni and FSDP1 run with
actor_rollout_ref.actor.veomni_config.param_offload=False,actor_rollout_ref.actor.veomni_config.optimizer_offload=True, andSP=1.
Full-Model Training - Zero Standard Deviation Ratio and Reward Curve
Training - Clip Fraction
Full-Model Validation Reward Curve
FlowDPPO: LoRA Training on Qwen-Image OCR
All experiments used NVIDIA H200 GPUs, LoRA rank 64,
ppo_micro_batch_size_per_gpu16, and the full 1k validation set. Training images per step = batch size × images per prompt = 32 × 16 = 512.
Script |
# GPUs |
# GPUs for Actor |
# GPUs for Rollout |
# GPUs for Async Reward |
Batch Size |
Images per Prompt |
LR |
Throughput (images/GPU/s) |
Time per Step (s) |
|---|---|---|---|---|---|---|---|---|---|
|
4 |
4 |
4 |
0 (sync) |
32 |
16 |
3e-4 |
0.240 |
540 |
LoRA Validation Reward Curve
DiffusionNFT: non-CFG LoRA Training on Qwen-Image OCR
All experiments used NVIDIA H200 GPUs, LoRA rank 64,
ppo_micro_batch_size_per_gpu16, and the full 1k validation set. Training images per step = batch size × images per prompt = 32 × 16 = 512.
Script |
# GPUs |
# GPUs for Actor |
# GPUs for Rollout |
# GPUs for Async Reward |
Batch Size |
Images per Prompt |
LR |
Throughput (images/GPU/s) |
Time per Step (s) |
|---|---|---|---|---|---|---|---|---|---|
|
4 |
4 |
4 |
0 (sync) |
24 |
12 |
3e-4 |
0.175 |
550 |
Reference wandb curve here.
LoRA Validation Reward Curve
GSPO OPD: Qwen3-Omni-30B-A3B training on 32xNPU (2 x Atlas 800T A3)
Experiments used Atlas 800T A3 NPUs, LoRA rank 32 applied to attention linear modules,
train_batch_size=128and rolloutn=16per prompt, and the full 2k validation set.
We add Gaussian noise (σ = 0.25·∥W∥) to the weights of Qwen3-Omni-30B-A3B-Instruct as the student model, while keeping the original un-noised model as the teacher. Both models are served by vllm_omni in AR mode. We compare the proposed OPD (Offline Preference Distillation) against a standard GSPO baseline, which trains the same noised Qwen3-Omni model directly under identical settings.
Script |
# NPUs |
# NPUs for Actor |
# NPUs for Rollout |
# NPUs for Teacher Model |
# NPUs for Async Reward |
Batch Size |
Rollouts per Prompt |
LR |
Time per Step (s) |
|---|---|---|---|---|---|---|---|---|---|
|
32 |
16 |
16 |
16 |
0 (sync) |
128 |
16 |
3e-6 |
1800 |